We kept the subject for 30 days instead of keeping the conversation
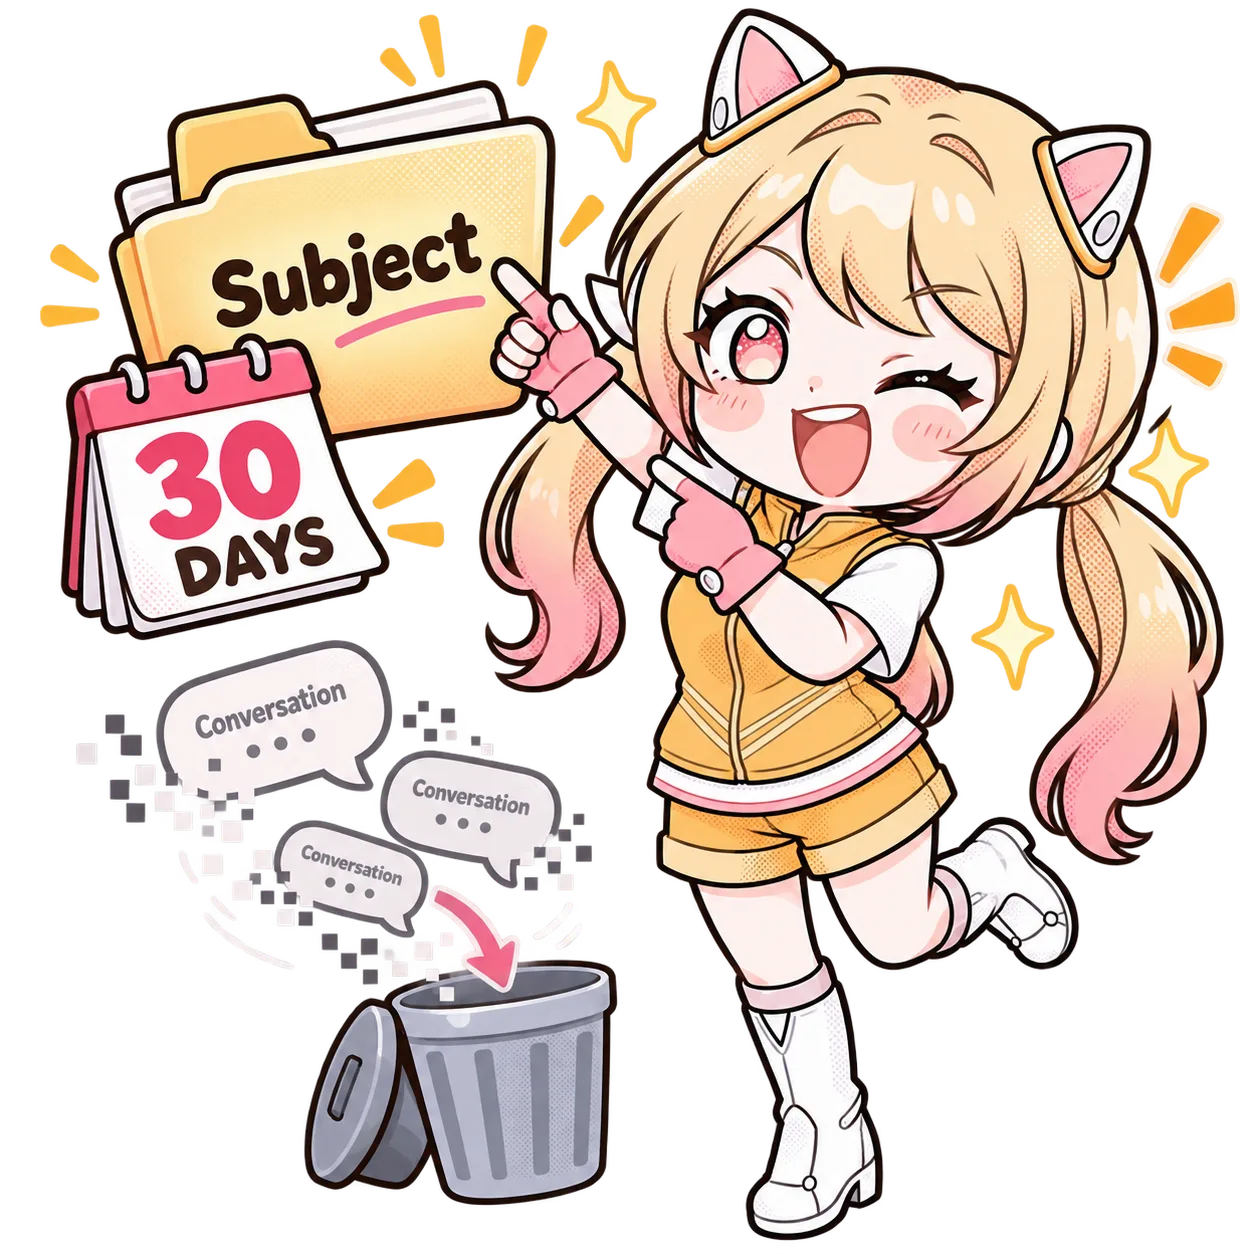
A shopper returned the next morning with the same session but without yesterday's transcript. Instead of retaining more conversation, we kept only the subject of a successful product search for the session's 30-day lifetime.
A shopper came back the next morning and asked, "มีอะไรใหม่ไหม" - anything new?
The day before, they had been looking at DAN DA DAN. Their browser still carried the same shopping session. But the assistant answered as if they had never met.
Nothing had crashed. Three clocks simply disagreed. Our widget kept its session id for 30 days. The server-side transcript expired after 24 hours. Conversation data had its own 90-day anonymisation window. By the next morning the shopper still looked like the same session to the widget, but the model no longer had the conversation that gave "anything new?" its meaning.
The obvious fix was to keep more conversation. We decided not to.
A longer transcript was the wrong kind of memory
Keeping yesterday's messages for longer sounds like the direct solution. If the assistant needs yesterday's context, give it yesterday's transcript. But the transcript was already read twelve messages at a time. Even if we extended its lifetime, five turns today could push yesterday's useful context out of the window anyway.
A longer lifetime therefore would not guarantee better continuity. It would guarantee something else: more old conversation available to store and more text potentially competing for prompt space. Every shop would also pay the token cost of carrying that history through future turns, whether the shopper needed it or not.
The problem was not really that we needed the conversation back. We needed one much smaller fact from it: what the shopper had been looking for. That changed the design.
We remembered the subject, not the conversation
When a shopper searches for something and the search actually matches, we keep the subject that search produced. Not the message, not the shopper's identity, and not their order. Just the subject that made the successful search useful.
That small record lives separately from the transcript and expires with the widget's 30-day session. It therefore lasts long enough to bridge the gap that caused the next-morning failure without turning the entire conversation into long-term memory.
There is an important qualification in that rule: only a search that matched is remembered. A miss is ambiguous. It might be a typo. It might be a product the store does not carry. It might be a badly phrased query that the shopper immediately abandons. Treating every miss as an enduring interest would turn failed retrieval into personalisation.
We chose the narrower signal. A successful product search says something useful happened around this subject. A failed one does not say enough.
Memory is useful only when the current question needs it
Keeping a subject created another risk. Once an assistant remembers something, it becomes tempting to demonstrate that memory. That is not the behaviour we wanted.
The stored subject is written to be ignorable. It should be used only when it fits what the shopper is asking now. It should never be brought up unprompted, and the assistant should never announce that it remembers the shopper.
That matters because continuity and surveillance can look surprisingly similar from the other side of the chat. "Anything new?" after yesterday's DAN DA DAN search is a continuity problem. The old subject can make the new question intelligible.
"Hello" is different. Responding to that greeting with an unsolicited reminder about yesterday's DAN DA DAN search would turn the same memory from useful context into something the shopper never asked to revisit. The memory therefore does not get to drive the conversation merely because it exists. The newest message still decides what the conversation is about.
Less memory gave us the behaviour we actually wanted
The interesting tradeoff was that keeping less produced a more useful form of memory. A transcript is rich. It contains exact wording, detours, abandoned questions and everything else said around the useful fact. That richness can be valuable while a conversation is happening, but it does not follow that all of it should become the thing that survives between visits.
The durable record we needed was much smaller. The shopper had looked for DAN DA DAN. The search had matched. If tomorrow's message depended on that subject, the assistant could use it. If tomorrow's message did not, the record could sit silently until it expired.
That was enough to solve the failure we had actually observed. It also kept different kinds of data doing different jobs. Conversation history could remain conversation history. The longer-lived shopping context could contain only the subject required for continuity. Identity and order information did not need to be pulled into that memory just because they might have appeared somewhere else in the session.
A shopping assistant does not need to remember everything to stop feeling forgetful
Long-term memory is increasingly treated as a defining capability of AI assistants. For a shop assistant, that framing can lead quickly to a bigger-is-better design: more history, more customer data, more persistent context.
Our next-morning shopper pushed us in the opposite direction. They did not need the assistant to reconstruct yesterday's conversation. They needed "anything new?" to still have a subject. So that is what we kept.
The result is a narrower definition of memory than simply preserving chat history. Some information belongs to the active conversation. Some belongs to the store's live systems. Some small pieces of context can survive a session boundary because they make a later question understandable.
Those categories do not need to collapse into one permanent customer record. The useful question for us became not "How much can the assistant remember?" but "What is the smallest thing it needs to remember for the next conversation to make sense?"
For this shopper, the answer was not twelve old messages. It was DAN DA DAN.